For years, the standard operating procedure for processing incoming documents was straightforward: a person opened the file, read it, categorized it, and passed it along. This worked reasonably well when document volumes were manageable and the cost of errors was absorbed quietly into overhead. But the conditions that made manual review acceptable have changed significantly. Software teams working across finance, healthcare, legal operations, and enterprise platforms are now dealing with document volumes and processing expectations that human review pipelines were never designed to handle at scale.
The shift away from manual review is not happening because of any single technology breakthrough. It is happening because the cumulative cost of inconsistency, processing delays, and human error has become difficult to ignore. When a document is misclassified or missed entirely, the downstream effects can affect billing cycles, compliance audits, customer records, and service delivery. The tolerance for that kind of operational drag has narrowed considerably, particularly for teams building or maintaining software that other businesses depend on.
What Document Detection Actually Does in a Production Environment
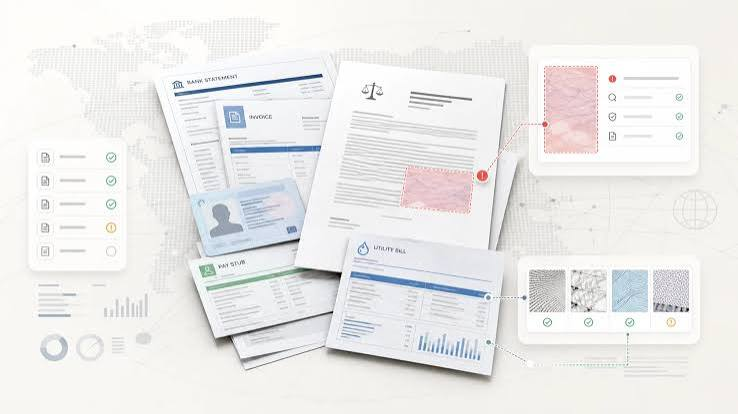
Document detection is the process by which a system identifies, classifies, and extracts relevant information from documents without requiring a person to manually read and interpret each one. It operates on the logic that documents — whether scanned, photographed, uploaded as PDFs, or transmitted electronically — contain structured and semi-structured data that a well-configured system can reliably recognize and act on. Unlike simple text search or keyword matching, modern document detection accounts for layout variation, formatting inconsistencies, and document type differences in a way that scales consistently across large input volumes.
For software teams, the practical value of document detection is not just speed — it is the removal of variability from a process that, when left to manual effort, produces different outcomes depending on who is doing the reviewing, how busy they are, and how familiar they are with the document type in question. A system configured correctly applies the same logic to every document it processes, which means the tenth thousand document is handled the same way as the first.
The Reliability Problem with Manual Review at Scale
Manual review introduces variability at every step. A reviewer who processes invoices in the morning after a clear briefing will make different decisions than one working through a backlog late in a shift, operating under different assumptions about edge cases. This is not a criticism of individual performance — it reflects a structural limitation of any process that depends entirely on human attention applied consistently across high volumes.
When that variability lives inside a software pipeline, it creates downstream unpredictability. Developers and product managers building integrations or automations around document processing have to account for the fact that the same input might produce different outputs depending on who touched it. This makes it harder to build reliable workflows and more difficult to provide consistent service to end users or enterprise clients.
Where Automated Detection Handles What Manual Review Cannot
There are document types and volumes that manual review simply cannot process within the timeframes modern operations require. Contract processing, medical record management, mortgage application handling, and insurance claims all involve large document sets that need to be processed quickly, categorized accurately, and routed to the right downstream systems without delay.
Automated document detection handles these scenarios by applying consistent classification logic to every document in the queue, regardless of how many arrive at once. It does not slow down because of volume, and it does not introduce errors because of fatigue. For software teams responsible for processing pipelines that serve external clients, this kind of reliability is not a preference — it is a product requirement.
The Operational Gap Between What Manual Review Promises and What It Delivers
There is often a gap between how manual review processes are described in internal documentation and how they actually perform in practice. Teams may have review protocols in place that specify turnaround times, accuracy standards, and escalation procedures. But those protocols assume consistent staffing, consistent training, and consistent document types — conditions that rarely hold over time.
Staff turnover means institutional knowledge gets lost. Document formats change as vendors, partners, or clients update their systems. Review backlogs grow during high-volume periods and create delays that affect other parts of the business. Each of these factors introduces risk that is difficult to measure in real time but becomes visible in audit outcomes, client complaints, and operational exceptions.
How Software Teams Identify the Breaking Point
For most software teams, the decision to move away from manual review does not come from a strategic planning exercise. It comes from a specific operational failure or a pattern of failures that becomes impossible to manage quietly. A client escalates because their documents were not processed within the agreed window. An audit reveals that a classification error caused data to be recorded incorrectly across a batch of records. A new client onboarding doubles the document volume, and the existing process cannot absorb it without hiring, which takes time the team does not have.
These are the conditions under which teams begin to evaluate what a more systematic approach would look like. The question is not whether automation is theoretically better than manual review — by most measurable criteria, it is. The question is what it takes to configure and integrate a detection layer that performs reliably within an existing system architecture.
Integration Considerations That Manual-First Teams Often Overlook
One reason some software teams hesitate before moving to automated document detection is the assumption that integration will be complex or disruptive. In practice, the integration challenge is real but manageable if approached with a clear understanding of what the system needs to handle and what outputs are expected.
The more significant planning requirement involves defining the document types the system will encounter, establishing how exceptions should be handled, and determining what happens when the system encounters a document it cannot confidently classify. These are workflow design questions, not purely technical ones, and teams that answer them clearly before implementation tend to see more stable outcomes after deployment.
Why US Software Teams in Particular Are Driving This Shift
The move away from manual document review is happening across international markets, but it is particularly pronounced among US-based software teams for several reasons. Regulatory environments in sectors like healthcare and financial services — governed by frameworks such as those maintained by the US Department of Health and Human Services under HIPAA — require documentation accuracy and traceability that manual processes struggle to provide consistently.
Beyond compliance, the enterprise software market in the US has matured to a point where clients expect document-related features — intake, classification, extraction — to be handled with the same reliability as any other core system function. Offering manual review as the backbone of a document processing feature is increasingly difficult to defend in sales conversations or service level agreements.
The Competitive Pressure on Product Teams
Software product teams are also responding to pressure from clients who have begun to expect faster turnaround times across all document-intensive workflows. When competing products process documents in near real-time and route data automatically, a product that requires manual review at any stage of the process looks less capable by comparison — regardless of how accurate that manual process is.
This dynamic is pushing even smaller software teams to prioritize document processing capability earlier in their product development cycles. What was once considered a back-office function is now treated as a core feature with direct implications for client retention and market positioning.
Risk Management as a Driver of Adoption
Perhaps the most underappreciated reason US software teams are moving toward automated document detection is risk management. Manual review carries liability. If a document is misclassified and that error causes a compliance violation, data breach, or contract dispute, the organization that operated the manual process bears responsibility for the failure. Automation does not eliminate risk, but it makes the process auditable. Every decision the system makes can be logged, reviewed, and traced — something that is structurally much harder to achieve with human review at scale.
• Automated systems produce consistent logs of every classification decision, making audits straightforward and defensible.
• Errors in automated systems are systematic rather than random, which means they can be identified and corrected at the configuration level rather than through individual retraining.
• Processing speed and accuracy can be measured and reported to clients or compliance officers with specificity that manual processes cannot easily match.
• Volume spikes do not degrade performance in the same way they degrade human review capacity, reducing the operational risk associated with growth or seasonal demand.
Closing Thoughts
The move from manual document review to automated detection reflects a practical reckoning with what it actually costs to process documents at scale through human effort alone. It is not about replacing people with technology for its own sake. It is about building systems that perform consistently, produce auditable outcomes, and do not introduce variability into workflows that affect clients, compliance, and product quality.
For US software teams in particular, the pressure to make this shift is coming from multiple directions at once — regulatory requirements, client expectations, competitive dynamics, and internal risk management concerns. The teams that have already made the transition tend to describe it less as a dramatic transformation and more as the removal of a persistent operational drag that had been treated as unavoidable for too long.
Manual review still has a place in exception handling, quality assurance, and edge cases that automated systems are not yet equipped to resolve confidently. But as the foundational layer of a document processing pipeline, it no longer holds up against what modern software operations actually demand. That is why the shift is happening, and why it is unlikely to reverse.
